https://leetcode.com/problems/lru-cache/?utm_source=chatgpt.com
LRU Cache - LeetCode
Can you solve this real interview question? LRU Cache - Design a data structure that follows the constraints of a Least Recently Used (LRU) cache [https://en.wikipedia.org/wiki/Cache_replacement_policies#LRU]. Implement the LRUCache class: * LRUCache(int c
leetcode.com
AI 발전으로 인해 코딩테스트 자체를 보지 않는 기업들도 늘어나고 있습니다.
하지만 그럼에도 불구하고, 면접 혹은 손코딩 등등 어려운 문제가 아니더라도 기본적인 자료구조 구현 등 코딩테스트를 통해서 얻을 수 있는 이점은 여전히 존재하고 있습니다.
오늘은 LRU를 구현해보았습니다.
먼저 1번 방법입니다.
class Node
{
public:
    Node() {};
    Node(int key, int value) : k(key), v(value)
    {
    };

    int k, v;
    Node* prev;
    Node* next;
};

class LRUCache {
public:
    LRUCache(int capacity) : _capacity(capacity), cursize(0){
        head->next = tail;
        tail->prev = head;
    }

    int get(int key) {
        Node* cur = head;
        while (cur != tail)
        {
            if (cur->k == key)
            {
                cur->prev->next = cur->next;
                cur->next->prev = cur->prev;

                cur->prev = head;
                cur->next = head->next;

                head->next->prev = cur;
                head->next = cur;

                return cur->v;
            }
            cur = cur->next;
        }
        return -1;
    }

    void put(int key, int value) {
        Node* cur = head;
        while (cur != tail)
        {
            if (cur->k == key)
            {
                cur->v = value;
                cur->prev->next = cur->next;
                cur->next->prev = cur->prev;

                cur->prev = head;
                cur->next = head->next;

                head->next->prev = cur;
                head->next = cur;

                return;
            }
            cur = cur->next;
        }

        if (cursize == _capacity)
        {
            Node* temp = tail->prev;
            tail->prev = tail->prev->prev;
            tail->prev->next = tail;
            delete temp;
            --cursize;
        }
        Node* newNode = new Node(key, value);
        newNode->next = head->next;
        newNode->prev = head;
        head->next->prev = newNode;
        head->next = newNode;
        ++cursize;
    }

    Node* head = new Node;
    Node* tail = new Node;
    int _capacity, cursize;
};
기본적으로 최근에 사용한 key-value쌍(이하Node)을 Recent Used로 놓아야하기 때문에 순서 변경이 자주일어날 것이라고 생각했고, 따라서 Linked List를 사용하기로 결정했습니다.
그에 따라 기본적인 Doubly Linked List를 구현했습니다. 정답자체는 맞았지만 성능이 전체중에서도 하위10퍼에 드는 문제있는 코드였습니다.
2번 방법입니다.
일단은 매번 new하고 delete하는 것에서 heap을 자주 접근하게되기 때문에 이 할당과정을 줄이고자 capacity만큼의 메모리를 미리 확보한 뒤 이를 활용하도록 했습니다.
class LRUCache {
public:
    LRUCache(int capacity) : _capacity(capacity), cursize(0){
        head->next = tail;
        tail->prev = head;

        for (int i = 0; i < capacity; ++i)
        {
            Node* newNode = new Node;
            newNode->next = head->next;
            newNode->prev = head;
            head->next->prev = newNode;
            head->next = newNode;
        }
    }

    int get(int key) {
        Node* cur = head;
        while (cur != tail)
        {
            if (cur->k == key)
            {
                insert_front(cur, key, cur->v);
                return cur->v;
            }
            cur = cur->next;
        }
        return -1;
    }

    void put(int key, int value) {
        Node* cur = head;
        while (cur != tail)
        {
            if (cur->k == key)
            {
                insert_front(cur, key, value);
                return;
            }
            cur = cur->next;
        }
        Node* temp = tail->prev;
        insert_front(temp, key, value);
    }

    void insert_front(Node* pNode, int key, int value)
    {
        pNode->k = key;
        pNode->v = value;

        pNode->prev->next = pNode->next;
        pNode->next->prev = pNode->prev;

        pNode->prev = head;
        pNode->next = head->next;

        head->next->prev = pNode;
        head->next = pNode;
    }

    Node* head = new Node;
    Node* tail = new Node;
    int _capacity, cursize;
};
이 방법을 통해 메모리 약간과 속도가 약간 개선되었지만 여전히 하위의 성능을 가졌습니다.
문제 사이트에서 제안한 방법으로는 find(순회)방법을 바꾸는 것이었습니다.
생각해보니 map으로 조회하면 성능이 향상될 것으로 보였습니다.
3번 방법입니다.
순서가 상관없기 때문에 Hash기반인 unordered_map을 사용했습니다.
find를 nodeMap을 통해서 하기 때문에 속도의 개선이 기대되었습니다. 다만 이전 코드를 계승해 여전히 아쉬운 느낌이 남았습니다.
class Node
{
public:
    Node() {};
    Node(int key, int value) : k(key), v(value)
    {
    };

    int k, v;
    Node* prev;
    Node* next;
};

class LRUCache {
public:
    LRUCache(int capacity) : _capacity(capacity){
        head->next = tail;
        tail->prev = head;

        for (int i = 0; i < capacity; ++i)
        {
            Node* newNode = new Node;
            newNode->next = head->next;
            newNode->prev = head;
            head->next->prev = newNode;
            head->next = newNode;
        }
    }

    int get(int key) {

        if (nodeMap.find(key) == nodeMap.end())
            return -1;
        insert_front(nodeMap[key], key, nodeMap[key]->v);
        return nodeMap[key]->v;
    }

    void put(int key, int value) {

        if (nodeMap.find(key) == nodeMap.end())
        {
            Node* temp = tail->prev;

            if (nodeMap.size() == _capacity)
            {
                nodeMap.erase(temp->k);
            }

            insert_front(temp, key, value);

            nodeMap.insert({ key, temp });
        }
        else
        {
            insert_front(nodeMap[key], key, value);
        }
    }

    void insert_front(Node* pNode, int key, int value)
    {
        pNode->k = key;
        pNode->v = value;

        pNode->prev->next = pNode->next;
        pNode->next->prev = pNode->prev;

        pNode->prev = head;
        pNode->next = head->next;

        head->next->prev = pNode;
        head->next = pNode;
    }

    Node* head = new Node;
    Node* tail = new Node;
    int _capacity;

    unordered_map<int, Node*> nodeMap;
};
성능은 크게 개선되어, 65퍼센트의 유저들보다 좋은 성능을 보여주는 코드가 되었습니다.
다만 그래프가 최빈값을 가지는 성능과는 떨어져있어 개선여지가 많이 남아있다고 생각했습니다.
4번 방법입니다.
이번에는 AI의 도움을 받아 개선점을 찾아냈습니다.
1. new[]활용 : new를 할 때 Node크기를 capacity번 만큼 확보하고 있었는데, new[]를 통해 한번에 sizeof(Node)*capacity 만큼 메모리를 확보하는 방법입니다.
heap자체에 접근이 적어지기 때문에 성능 개선이 예상되었습니다.
2. map reserve, map의 용량도 미리 capcacity만큼 확보하는 것입니다. 이것도 미리 확보하는 개념일 것입니다.
3. find시에 중복조회 제거: find후에 다시 []로 조회하고 있었습니다. operator []를 통해 하는 횟수를 줄여 hash lookup회수를 줄입니다.
#include <unordered_map>

using namespace std;

class Node
{
public:
    Node() : k(0), v(0), prev(nullptr), next(nullptr) {}
    Node(int key, int value)
        : k(key), v(value), prev(nullptr), next(nullptr)
    {
    }

    int k, v;
    Node* prev;
    Node* next;
};

class LRUCache {
public:
    LRUCache(int capacity)
        : _capacity(capacity)
    {
        head = new Node;
        tail = new Node;

        head->next = tail;
        tail->prev = head;

        // unordered_map의 rehash 최소화
        nodeMap.reserve(capacity);

        // Node를 하나씩 new 하지 않고 한 번에 할당
        nodePool = new Node[capacity];

        for (int i = 0; i < capacity; ++i)
        {
            Node* newNode = &nodePool[i];

            newNode->next = head->next;
            newNode->prev = head;

            head->next->prev = newNode;
            head->next = newNode;
        }
    }

    ~LRUCache()
    {
        delete[] nodePool;
        delete head;
        delete tail;
    }

    int get(int key)
    {
        auto it = nodeMap.find(key);

        if (it == nodeMap.end())
            return -1;

        Node* pNode = it->second;

        move_front(pNode);

        return pNode->v;
    }

    void put(int key, int value)
    {
        auto it = nodeMap.find(key);

        // 이미 존재하는 key
        if (it != nodeMap.end())
        {
            Node* pNode = it->second;

            pNode->v = value;

            move_front(pNode);

            return;
        }

        // 가장 오래 사용되지 않은 Node
        Node* temp = tail->prev;

        // 캐시가 꽉 찬 경우 기존 key 제거
        if (nodeMap.size() == _capacity)
        {
            nodeMap.erase(temp->k);
        }

        temp->k = key;
        temp->v = value;

        move_front(temp);

        nodeMap.emplace(key, temp);
    }

    void move_front(Node* pNode)
    {
        // 기존 위치에서 제거
        pNode->prev->next = pNode->next;
        pNode->next->prev = pNode->prev;

        // head 바로 뒤에 삽입
        pNode->prev = head;
        pNode->next = head->next;

        head->next->prev = pNode;
        head->next = pNode;
    }

private:
    Node* head;
    Node* tail;
    Node* nodePool;

    int _capacity;

    unordered_map<int, Node*> nodeMap;
};
이 방법을 통해서도 큰 성능개선을 볼 수 있었고, 이제야 유저들의 최빈값 풀이에 도달할 수 있었습니다.
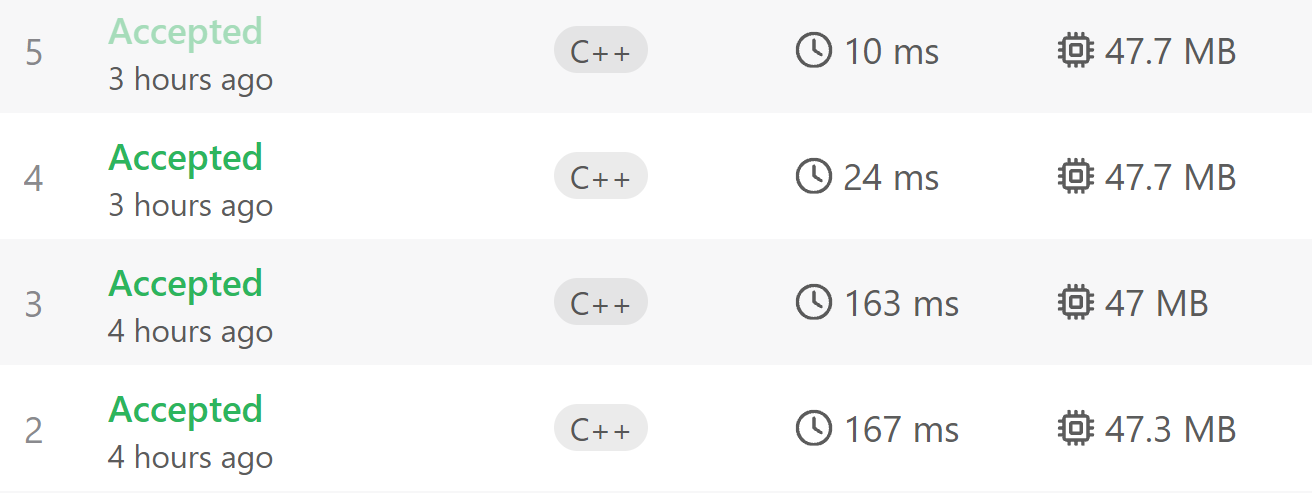
방법은 역순으로 보시면 됩니다.
4, 5번에서는 map을 활용하기에 아주 약간의 메모리가 더 활용되었습니다.
'Algorithm > PS' 카테고리의 다른 글
| [Leetcode] Longuset Substring Without... 풀어보기 (0) | 2026.09.18 |
|---|---|
| [Leetcode] Kth Largest Element 풀어보기 (0) | 2026.09.17 |
| [알고리즘] 미로탈출 (0) | 2026.08.12 |
| [알고리즘 풀이] 구명보트 (0) | 2026.08.06 |
| [알고리즘] 괄호 회전하기 (0) | 2026.07.10 |